Vs. Random Test:
How to Detect a "Lucky" Backtest
The hardest part isn't building a good-looking backtest. It's knowing whether that backtest has real edge. Or is simply the best-looking result from a lot of random noise.
What Is the Vs. Random Test?
The Vs. Random test is a robustness check that answers one question: "Could I have achieved similar results by luck?"
That question is the heart of data mining bias: the more strategies you test, the better the best one looks by chance alone.
Instead of comparing your strategy to "buy & hold" or a benchmark index, you compare it to a far more uncomfortable opponent: the best strategy produced by randomness under the same constraints. If your real strategy forces trading between a certain time window or forces an exit at end of day then the random strategies will adopt that constraint for an apples-to-apples comparison of what is possible in the same circumstances.
We mine the data for random strategies with random signals and find the best one. If your real strategy can't exceed this baseline in a meaningful way, there's a strong chance it is overfit to historical noise, exploiting data quirks, or simply a statistical fluke.
Origin
This concept is widely associated with Jaffray Woodriff of Quantitative Investment Management and was popularized through his chapter in Hedge Fund Market Wizards. The idea is simple and brutally honest: build the best strategies you can using random data and random signals, then use the best "random strategy" as the baseline. If your strategy can't beat it, there's unlikely a real edge.
This is why Vs. Random is best thought of as an anti-self-deception tool. It can help identify lying backtests and overfit results before we risk real capital. We want robust trading strategies, not lucky ones.
Why a Random Baseline Is So Powerful
If you generate enough strategies, you will eventually find a "winner" even if there is no real signal. This is just statistics: with enough trials, some outcomes will look exceptional by chance. Optimization amplifies this effect because it selects the best outcome from a large pile.
A strategy that looks great in a backtest may not be "good." It may just be the best survivor of randomness. A random baseline creates a controlled way to ask: "Is my strategy genuinely better than what randomness can produce?"
This principle applies to all forms of automatically generated trading strategies, whether built by hand or through a genetic algorithm.
How the Vs. Random Test Works
There are a few common implementations, but they generally fall into three buckets:
Keep the real market data. Replace your signals with random entries/exits. Optimize those random rules the same way. If the best random strategy looks similar to yours, that's a problem.
Keep your signal logic. Randomize or add noise to the underlying price series to break structure. Re-run/optimize. If performance holds on destroyed structure, you may be fitting noise.
Randomize both. Use the best result as an upper bound of what luck can generate. This becomes the harshest benchmark, useful for large strategy searches to avoid lying backtests.
Why Three Methods?
Trading is a game of removing as much risk as possible. The random generation process itself is a risk factor that can introduce biases. Using multiple random generators, randomizing signals, data, and both, provides a more robust benchmark. Risk management isn't just for executing trades but also for your development process.
What to Compare Against the Random Baseline
At minimum, compare: net profit / CAGR, max drawdown, Sharpe / Sortino, profit factor, win rate, average trade, equity curve shape, and trade count.
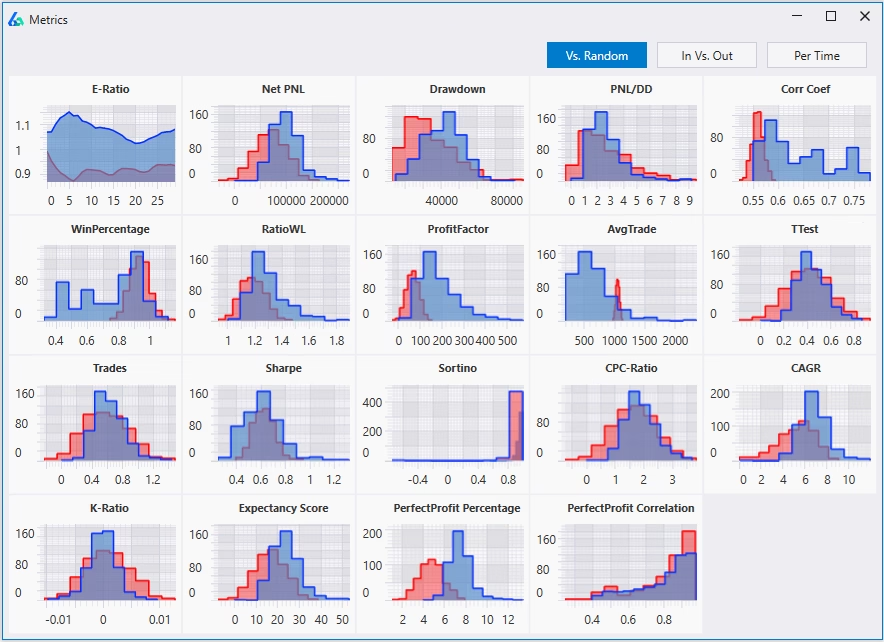
But the key insight: don't just compare any metric. Compare the metric you optimized for. If you optimize for Sharpe ratio, compare your Sharpe against the best Sharpe from the random process. That's why Build Alpha lets you view the real strategy distribution vs. the random distribution for all performance metrics.
How to Interpret Vs. Random Results
Most analysis using the Vs. Random test can be eyeballed, crazy talk from a quant, right? But we really only care if our strategy clearly beats the random baseline, which is easy to see on a chart.
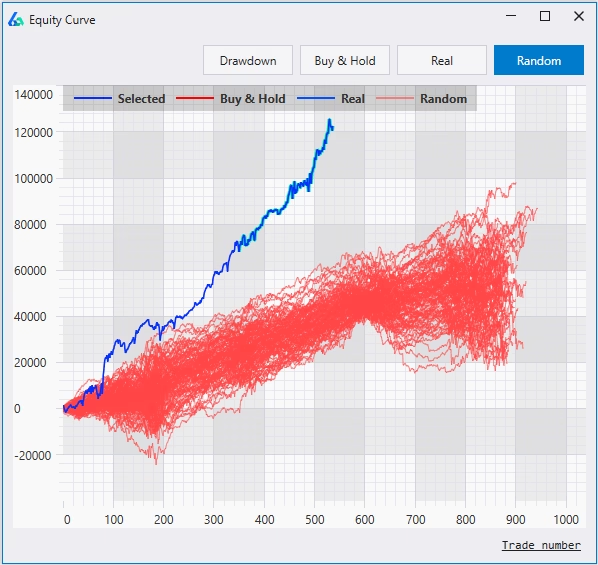
Blue equity curve (your strategy) is clearly above the red distribution (random). Doesn't guarantee success, but increases confidence the edge isn't explained by luck.
Better on profit but not on risk. Strategy is weak, search constraints too broad, over-optimizing, or the market is extremely noisy. Needs improvement.
Real strategy doesn't beat the best random result, or only beats it on cherry-picked metrics. Likely curve-fit or fragile. Avoid these strategies.
Case Study: Two Strategies, One Truth
In the Lying Backtests Case Study, two strategies with nearly identical backtest equity curves are put through the Vs Random test, and only one survives.
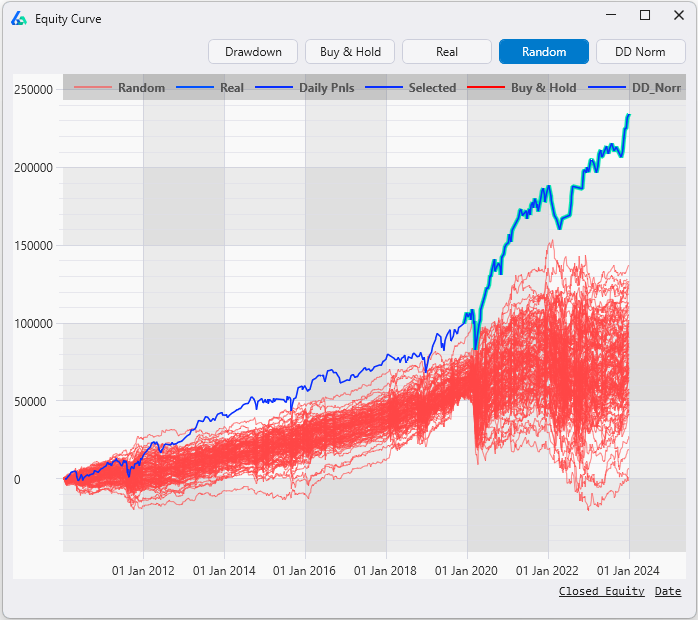
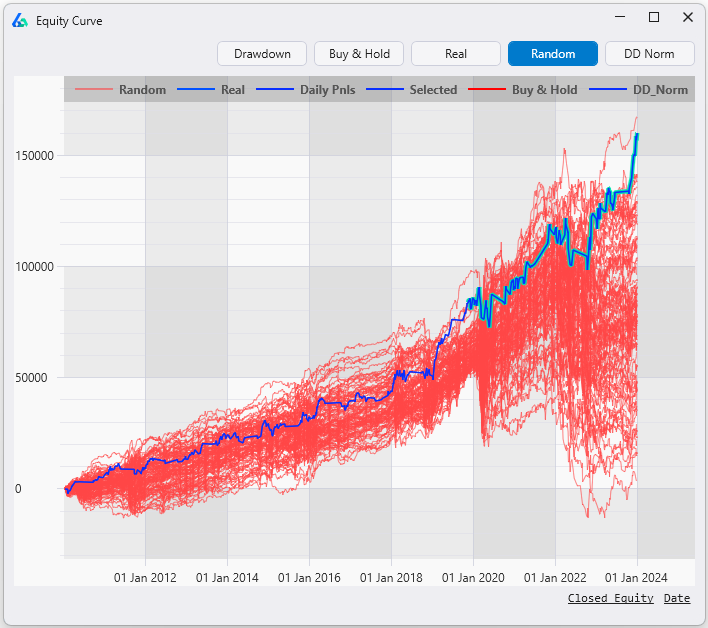
The forward performance confirmed the Vs Random verdict: Strategy A continued climbing through new data while Strategy B collapsed entirely. If your strategy can't beat random, there is no edge.
5 Common Mistakes
Comparing to "Average Random"
Don't compare to the average random strategy. Compare to the best random strategy. Your search selects the best, the correct comparison is best vs. best.
Not Matching Constraints
If your real strategy allows certain leverage, hold times, or exits, the random search must use the same constraints. Otherwise, you're not comparing like-to-like.
Not Matching Fitness
Optimizing for Sharpe ratio then comparing P&L to the random distribution is missing the mark. Compare the same metric you optimized for. Build Alpha provides this view for all performance metrics.
Ignoring Sample Size
Beating random over a tiny number of trades isn't convincing. Edge materializes over many trials. Think of a coin: 7 heads in 10 flips proves nothing. 7,000 heads in 10,000 flips is clearly rigged.
Treating a Pass as Proof
A pass means "less likely to be pure luck." You still need out-of-sample testing, Monte Carlo simulation, noise testing, and proper cost assumptions.
Where Vs. Random Fits in a Robustness Workflow
A simple order that works well for most traders:
Core Sanity Checks
Cost assumptions, minimum trades, avoid overly precise parameters. See fitness functions for objective selection criteria.
Out-of-Sample Validation
Split data 70/30. Full OOS guide →
Monte Carlo Simulation
Streaks + drawdown expectation. Full MC guide →
Noise Test
Detect fitting to noise. Full noise test guide →
Vs. Random Baseline ← You Are Here
Prove edge vs. luck.
Cross-Market Testing
Test on related markets (SPY → QQQ, DIA).
Walk-Forward (optional but strong)
Rolling re-optimization. Full WF guide →
Automated Workflows in Build Alpha
Build Alpha v3 supports automated workflows. You can set the Vs. Random test as a pass/fail filter before strategy generation begins. Build Alpha will only return strategies that beat the random baseline by your specified threshold.

Combine with automated noise test, Monte Carlo, and OOS filters and you have a complete validation pipeline. You review the small number of survivors, not hundreds of fragile backtests. More on the full trading strategy generator software workflow.
Practical Takeaway
If you generate enough strategies, you can "discover" profitability by accident. The Vs. Random test gives you a reality check:
✓ The Bottom Line
- If you can't beat the best random baseline, stop trusting the backtest.
- If you can beat it meaningfully, you've cleared a higher bar than most traders ever apply.
- That's how you reduce the odds of trading a "lucky" strategy disguised as skill.
Vs. Random Test FAQ
Related Deep Dives
David Bergstrom
A decade-plus in professional trading as a market maker and quantitative strategy developer at a high-frequency trading firm with a CME seat. Self-taught C++, C#, and Python programmer specializing in data science, machine learning, and trading strategy development.
What Traders Say About Build Alpha






Explore More
Stop Trading
"Lucky" Backtests.
Prove your strategy beats the best random baseline. 12+ robustness tests. No coding required.